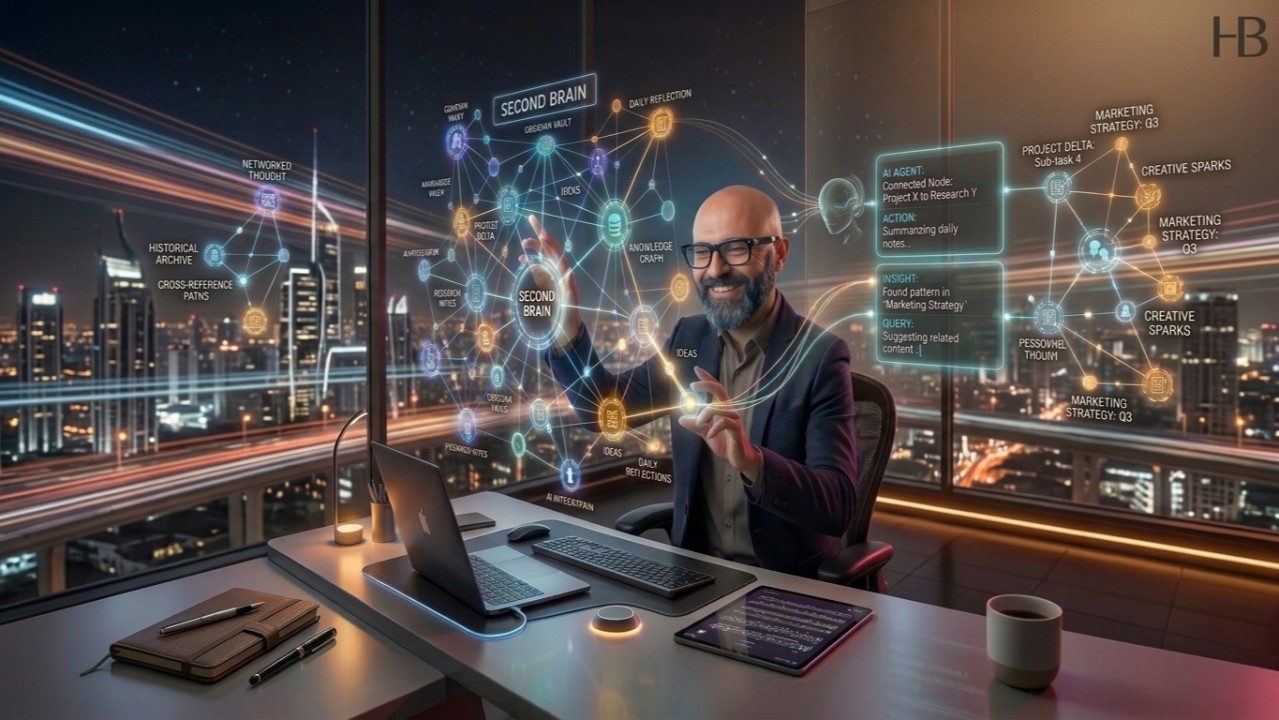
The problem was never note taking
I was not looking for yet another notes app. The problem was a different one, and I felt it every day: every time I open a chat with a model I have to start from nothing. Who I am. What I am building. How I think. What I have already tried and why it did not work.
Andrej Karpathy gave the way out a name: an LLM wiki. A persistent body of knowledge about you that the AI can consult as context, instead of asking you for it every single time.
The difference from a folder of notes is not cosmetic. A folder of notes exists to be re-read. An LLM wiki exists to be queried, including by a machine. That changes how you build it.
The rule that holds it together: every piece of information has one home
It is the only genuinely rigid principle in the whole system, and the only one you cannot negotiate once the vault grows.
Mine is split into areas, each answering a different question: work and clients, active projects, professional identity, external context about companies and people, ideas, content, personal life. Everything that comes in has exactly one destination, and if it seems to have two then one of them is wrong.
This sounds like pedantry. It is not, and here is why: that rigidity removes a micro-decision you otherwise pay twenty times a day. "Where do I put this?" repeated twenty times a day is the real friction cost, far more than the writing itself. When the answer is automatic you stop thinking about it and start writing.
The uncomfortable corollary: if the same fact appears on two pages, one of them is already out of date and you do not know it yet. From that point on the system starts lying to you, and memory is not what failed.
The librarian is not a prompt, it is a contract
I do not maintain the vault by hand. An agent works inside it, and what made the difference was not writing a better prompt: it was writing a document.
In the root of the vault there is a rules file the agent loads automatically at the start of every session. It does not say "help me with my notes". It says, in writing and once:
- how a page is created and how it links to the others
- the file naming conventions
- where each kind of information belongs, area by area
- what the agent must not touch without explicit permission
- the checkpoints where it has to stop and ask
The whole difference from a prompt is right there: you are not asking for an opinion, you are applying rules written once. A prompt gets rewritten every time and comes out slightly different every time. A contract gets corrected when it is wrong, and the correction holds forever.
What it does on its own
With that contract in place, three things happen without me steering them:
- Notes from a call: it creates the page, links the people and companies mentioned, updates the overview of the area involved
- End of session: it writes a journal entry in a fixed structure, what was done, what is still open, which decisions were taken and why
- A new document: it works out where it belongs, links it to what already exists, updates the indexes
The honest result: what changed and what did not
Let me start with what did not change, because that is the part nobody usually tells you. I did not get faster at email. I do not clear the task list before the evening. I did not gain a single minute.
What changed is something else. I walk into a meeting knowing exactly where we stand on a project: not because my memory is remarkable, but because three days ago I wrote down why we made that call. And when I reopen a session with the agent, the AI picks up where it left off, because the context is already written. No explain-it-all-again.
I did not become more productive. I became clearer. Those are two different things: productivity is a quantity, clarity is a quality, and months later I know which one I was actually short of.
Why it works: context engineering, not prompt engineering
This is the shift, and it fits in one line: a better prompt helps once, a better context helps every time after that.
The vault is not a passive archive I occasionally dig through. It is the memory I hand the model before it answers me. Prompt engineering solves the question I am asking right now. Context engineering solves the next year of questions, because every session starts from a system that already knows who I am, what I am building and what I have already ruled out.
The technical backstage
The part that never fit in a post, and the part people actually ask about.
Runtime and rules
The agent runs on Claude Code, which works on files rather than in a chat window. The rules file sits in the root of the vault and is loaded at every start: it is the contract above, and it is the only place the rules live.
The two skills I use every day
/avvia-sessione, start session: it reads the project context, looks for previous sessions and presents an up to date briefing before I have typed a line/chiudi-sessione, close session: it writes the day's journal entry in a fixed structure and updates the session index
They are trivial commands. The value is not in the command, it is in the journal always having the same shape, so that in six months it can still be read.
Obsidian to think, Notion to track
Not everything lives in the vault, and it should not. Structured data that changes state, content KPIs, job applications, open tasks, lives in Notion, and the agent keeps the two sides aligned. Obsidian is where you think, Notion is where you track, and blurring those two roles is the fastest way to end up with two systems that contradict each other.
Metadata, or the graph is just decoration
Every page carries mandatory YAML frontmatter: page type, area, tags, last updated date, the sources the knowledge came from. It serves one purpose, and it is an important one: making the system queryable and not merely readable. With metadata the link graph becomes useful. Without it, it is a poster.
Canonical sources outside the vault
Meeting dates are never written into pages. You create the calendar event and the page carries the link. It sounds like a detail and it is the rule that avoids the worst job of all, which is updating the same date by hand in four places and finding out later that one of them stayed wrong.
A lint, because otherwise it rots
A Python script walks the vault looking for missing or incomplete frontmatter, broken internal links, pages nobody links to, pages that have grown too long, parts of the graph disconnected from the rest. I run it before long sessions. It is free and it is objective, and it reliably finds things I no longer see because I work inside them every day.
You do not need all of this to start
You need very little, and starting small is the point: the one home rule and two or three real areas, not seven perfect ones. The rest gets added when it is genuinely needed.
A structure designed up front describes the work you imagine doing, not the work you do. Mine has changed several times, and every change came from real friction, never from planning.
Where it leads
The next step was to stop reading the vault and start letting it act: a personal agent that uses that knowledge not to answer in general, but to act in contexts it knows, under rules I wrote, on data that is mine. That, though, is another story, and a longer one.
Frequently asked questions
What is the difference between a second brain and a folder of notes?
A folder of notes is there to be re-read. An LLM wiki is there to be queried, including by a model. In practice the difference is three things: every piece of information has exactly one home, every page carries structured metadata, and the maintenance rules are written in a file rather than remembered.
Do you have to use Obsidian?
No. What matters is that the pages are plain text files on disk, with readable metadata and links between them. Obsidian is convenient because it is only a reader on top of a folder of Markdown: change tool tomorrow and the files are still yours, and the agent still reads them.
How does the AI actually read the vault?
You point a file-aware agent, such as Claude Code, at the vault folder. In the root there is a rules file that gets loaded at the start of every session and tells the agent how the structure works, where each kind of thing belongs, and what it must not touch without asking.
How long does it take to build?
Little to start and a lot to finish, which is precisely why you should not try to finish it. The single-home rule and two or three real areas are enough; the rest gets added when it is needed, because a structure designed up front describes the work you imagine, not the work you do.
What is the difference between prompt engineering and context engineering?
A better prompt helps once. A better context helps every time after that. The prompt solves the question you are asking now, the context solves the next year of questions, because the model starts out already knowing who you are, what you are building and what you have already tried.
What happens when the vault grows and gets messy?
You need an automated check, otherwise it rots. A script that looks for missing frontmatter, broken links, pages nobody links to and pages that have grown too long, run before long sessions, keeps the system readable without you having to think about it.
Holti Bitri
CTO & AI Innovator, TIG Factory. Nearly 20 years in the Microsoft ecosystem, today between cloud architectures, AI pipelines in production, and the craft of knowing when a model is wrong without telling you. LinkedIn · holtibitri.com